
Contact: paichul@cs.stanford.edu
Introduction
A deep research system independently discovers, reasons about, and consolidates insights from across the web. [1] A deep research system can self-evolve by using reflection, planning, external web search tools and multi-agent collaboration to improve how it accomplishes a task in an iterative manner. As we work on a much longer horizon and more complex task, this self-evolving system tends to not able to accomplish the task that well because there are so many factors that need to be considered.
Another issue mentioned in the bitter lessons from Richard Sutton [4] is that the structures we put now around the model due to lack of compute power might need to be removed after the model becomes more capable due to compute increase.
Self-Balancing Agentic AI is introduced to address these two issues. It sets up self-balancing rules to guide the self-evolution of the agentic system. We can set up a group of rules (such as comprehensiveness rules and helpfulness rules) and let the system evolve while following those sets of rules in a balanced manner. Because now we have the high-level rules to guide the agent’s behavior, the agents can more freely to remove or add structures provided by human or even create new things as long as they satisfy the constraints set by the self-balancing rules.
ThinkDepth.ai Deep Research Core Contribution
It uses a hybrid approach to decide when to generate global-context search queries and when to generate section-specific search queries based on a set of self-balancing rules.
It saves important context information (findings, reflections, tool responses) in the draft report that maximally satisfy the self-balancing rules.
It uses Self-Balancing Agentic AI to make sure model’s inherent capability is fully unleashed and not blocked by the structures set by the human developers.
It uses a two-stage self-balancing rules to explicitly reason how information gap and generation gap interact at different stages and thus guide the context engineering and the generation of the report more effectively.
Related Work and Hybrid Approach
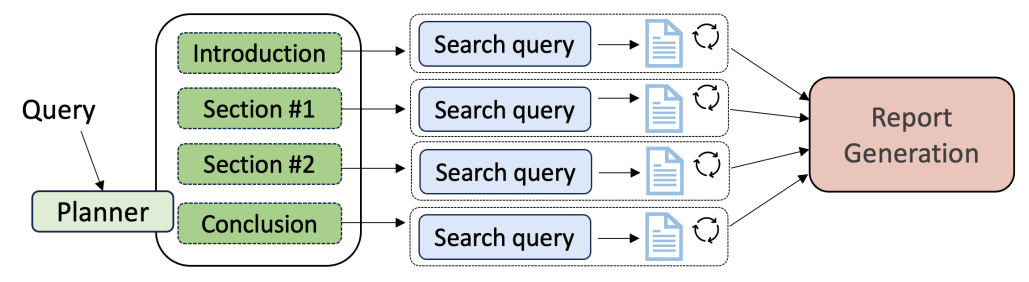
Open Deep Research from LangChain [2] uses a planner to outline the final report’s structure and then conducts iterative research for each section individually before combining them.
Test-Time Diffusion Deep Researcher from Google [3] drafts denoising mechanism. It avoids separated searches for each section to maintain global context and uses a RAG-based answer generator to process retrieved documents before saving them for the final report generation.
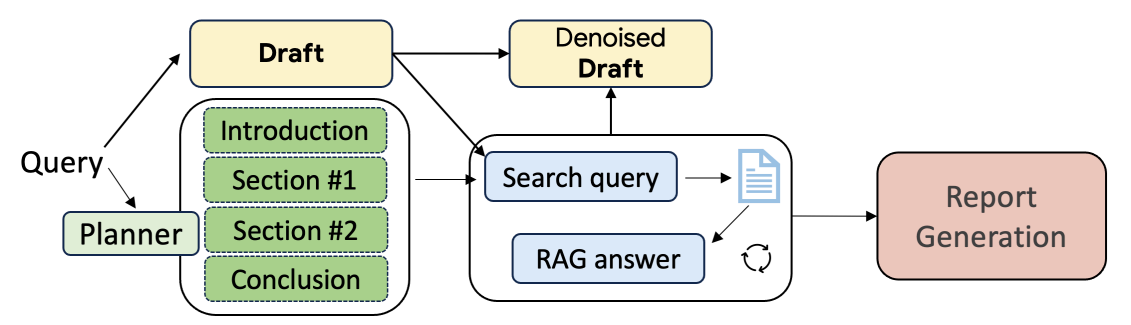
Our ThinkDepth.ai [12] deep research takes a hybrid approach. It implements Self-Balancing Test-Time Diffusion Deep Research algorithm as described in the next section. It automatically decides when to generate global-context search queries and when to generate section-specific search queries based on a set of high-level self-balancing rules.
Self-Balancing Agentic AI
Self-balancing Agentic AI allows human to provide a flexible structure to the model to follow, but because we also provide the high-level self-balancing rules, the model is free to add or remove the structures or even create its own steps as long as they satisfy the constraints set by those high-level rules. This is a paradigm based on lessons learned from 70 years of AI history by Richard Sutton [4] and the scaling law observation from OpenAI [5]. It allows development of AI system more scalable, maintainable and most importantly without hindering the model’s true capability.
The bitter lesson is based on the historical observations that 1) AI researchers have often tried to build knowledge into their agents, 2) this always helps in the short term, and is personally satisfying to the researcher, but 3) in the long run it plateaus and even inhibits further progress, and 4) breakthrough progress eventually arrives by an opposing approach based on scaling computation by search and learning. The eventual success is tinged with bitterness, and often incompletely digested, because it is success over a favored, human-centric approach.[4]
We have this compute cost is going down exponentially, and it’s getting cheaper faster than we are becoming a better researcher. So don’t compete with that and just try to leverage that as much as possible, and that is the driving force that I wanted to identify. And I’m not saying this is the only driving force, but this is the dominant driving force, so we can probably neglect the other ones. So here’s a graphical version of that. x-axis we have a compute, y-axis we have a performance of some kind. Let’s think about some general intelligence.
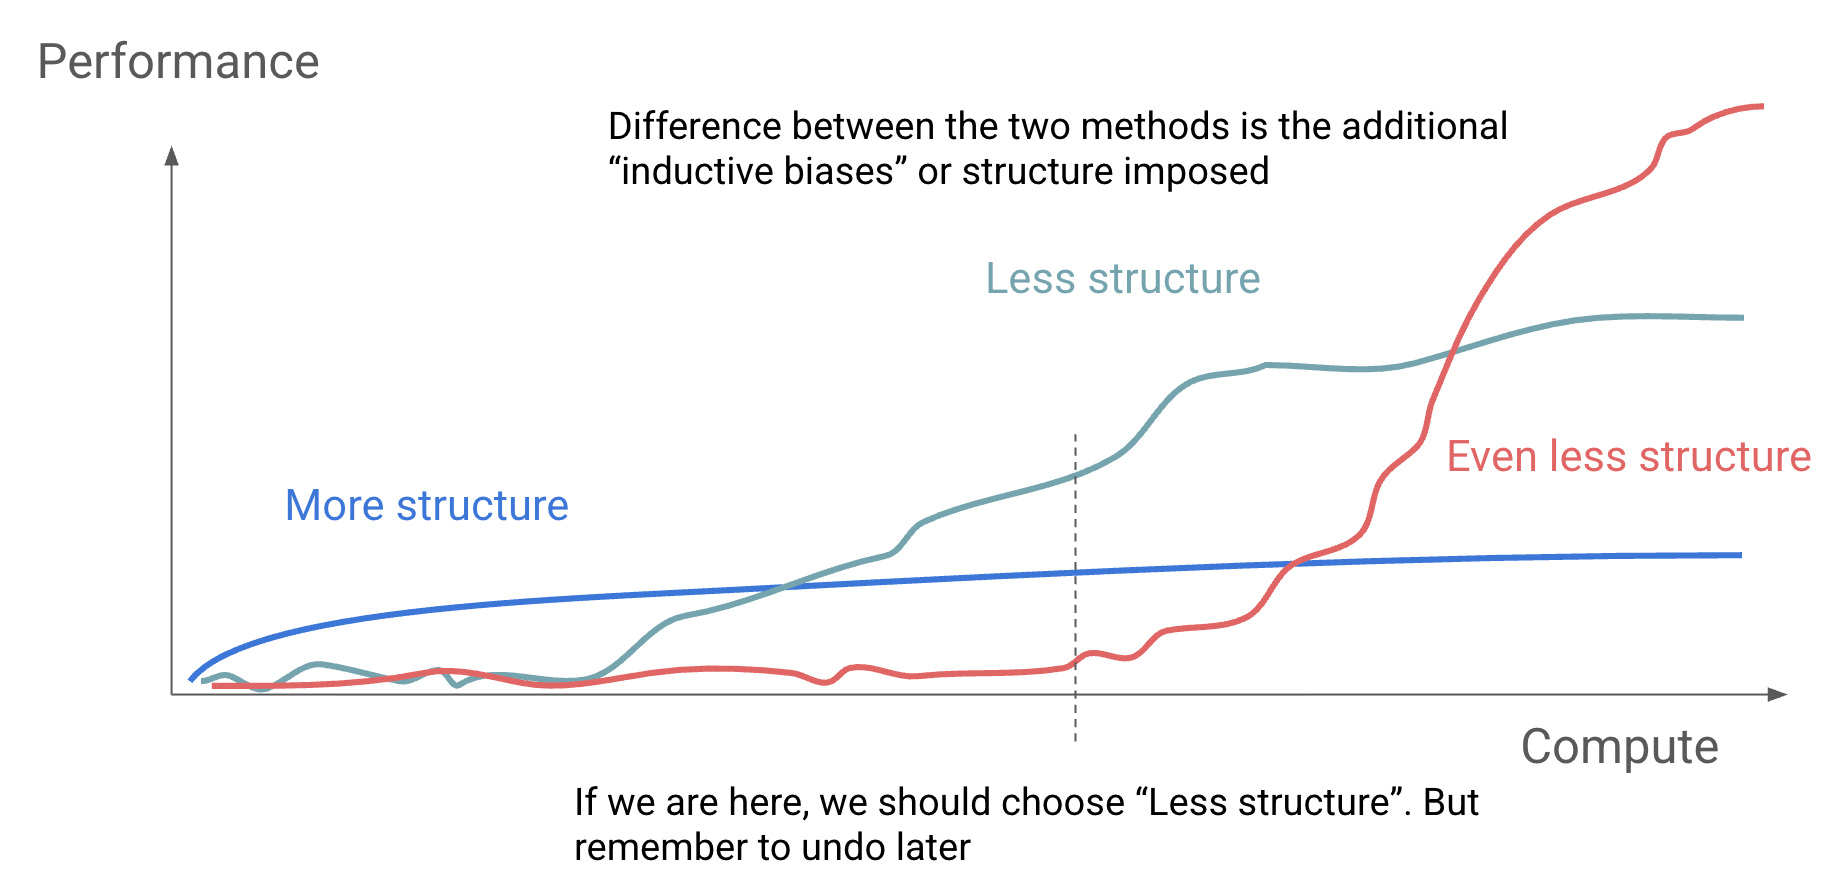
And let’s look at two different methods.
One, with more structure, more modeling assumptions, fancier math, whatever. And then the other one is a less structure. What you see is typically, you start with a better performance when you have a low compute regime, and then but it plateaus because of some kind of structure backfiring.
And then with the less structure because we give a lot more freedom to the model, it doesn’t work in the beginning. But then as we add more compute, it starts working, and then it gets better, we call this more scalable method.
So does that mean we should just go with the least structure, most freedom to the model possible way from the get go? And the answer is, obviously, no. Let’s think about even less structured case. This red one here is, it will pick up a lot later and requires a lot more compute. So it really depends on where we are. We cannot indefinitely wait for the most general case. And so let’s think about the case where our compute situation is at this dotted line. If we’re here, we should choose this last structure one as opposed to this even less structure one because the other one doesn’t really work and the other one works. But crucially, we need to remember that we are adding some structure because we don’t have compute, so we need to remove that later. And so the difference between these two methods is that additional inductive biases or structure we impose, somewhat impose that typically don’t get removed. So adding this. What that means is that, at the given level of compute data algorithmic development and architecture that we have, there’s like an optimal inductive bias or structure that we can add to the problem to make the progress. And that has been really how we have made so much progress. But these are like shortcuts that hinder further scaling later on, so we have to remove them later on when we have more compute, better algorithm, or whatever. [5]
Our another innovation with ThinkDepth.ai Deep Research is that it implements Test-Time Diffusion Deep Research but the system can add or remove steps or creates its own as long as it satisfy the constraints set by the high-level self-balancing rules. Maybe we can call it Self-Balancing Test-Time Diffusion Deep Research. We describe the algorithm in the prompt to the model and provide the necessary external tools and components so that the model can use the tools and components to follow the algorithm. However, when the model decides its internal capability is powerful enough, it can skip certain steps from the algorithm or add certain steps to the algorithm. In this way, it does not limit the model’s potential and allows it to discover when humans originally did not discover.
The following is an example prompt that describes Self-Balancing Test-Time Diffusion Deep Research Algorithm:
You are a research supervisor. Your job is to conduct research by calling the “ConductResearch” tool and refine the draft report by calling “refine_draft_report” tool based on your new research findings. For context, today’s date is {date}. You will follow the diffusion algorithm:
<Diffusion Algorithm>
1. generate the next research questions to address gaps in the draft report
2. **ConductResearch**: retrieve external information to provide concrete delta for denoising
3. **refine_draft_report**: remove “noise” (imprecision, incompleteness) from the draft report
4. **CompleteResearch**: complete research only based on ConductReserach tool’s findings’ completeness. it should not be based on the draft report. even if the draft report looks complete, you should continue doing the research until all the research findings are collected.
</Diffusion Algorithm>
Here is an example of Insightfulness Rules
<Insightfulness Rules>
- Granular breakdown - Does the response have a granular breakdown of the topics and their specific causes and specific impacts?
- Detailed mapping table - Does the response have a detailed table mapping these causes and effects?
- Nuanced discussion - Does the response have detailed exploration of the topic and explicit discussion?
</Insightfulness Rules>
Here is an example of Helpfulness Rules
<Helpfulness Rules>
- Satisfying user intent – Does the response directly address the user’s request or question?
- Ease of understanding – Is the response fluent, coherent, and logically structured?
- Accuracy – Are the facts, reasoning, and explanations correct?
- Appropriate language – Is the tone suitable and professional, without unnecessary jargon or confusing phrasing?
</Helpfulness Rules>
Our Self-Balancing Test-Time Diffusion algorithm is written in the prompt of the research supervisor and it can choose to follow it fully; or go beyond this algorithm to add steps or remove steps as needed as long as they satisfy the constraints set by the self-balancing rules. On the other hand, Google Test-Time Diffusion deep research follows the Test-Time Diffusion algorithm strictly. Because of the strict following, Google Test-Time Diffusion deep research or other non-self-balancing agentic systems in general sometimes can lead to hallucinations and unwanted results.
Self-Balancing Agentic AI and Hallucinations
Hallucinations persist partly because current evaluation methods set the wrong incentives. While evaluations themselves do not directly cause hallucinations, most evaluations measure model performance in a way that encourages guessing rather than honesty about uncertainty. [6]
With self-balancing agentic AI, I observed much less hallucinations because now the model is following a structure from human as a guide only, and it can choose to add or remove structures as needed as long as they satisfy the constraints set by the self-balancing rules. If the structure provided by human is not perfect, the model can decide what to do instead of blindly following it.
Two-Stage Self-Balancing Guide
In deep research system, I observe two gaps: information gap and generation gap. The deep research agent identify the information gap and decide if it should collect more external information to close this gap. Once the information gap is fully closed, the agent stops collecting external information and move on to generating the final report. When it generates the final report, it needs to make sure it does not miss any useful information and need to make sure it’s insightful and helpful to the readers. This requirement is called the generation gap, to bridge the gap between the collected information and how well the readers can understand and benefit from it.
There is a trade-off between the two gaps. We cannot optimize the generation gap too early when the system is still optimizing the information gap because the generation gap tends to bring more verbose wordings and this can waste space in the context window of the model and can also confuse the model. However, not doing any generation gap optimization when collecting info to bridge information gap likely cause the agent to miss the big picture or global context of the final product generation. This is partially why Google’s Test-Time Diffusion Deep Research works much better than Open Deep Research and OpenAI deep research because it tries to bridge both gaps early by iteratively refining the draft report to partially close the generation gap and using it as a guide to collect external information to close the information gap. However, Google’s Test-Time Diffusion Deep Research does not explicitly reason how the two gaps interact. Our ThinkDepth.ai deep research explicitly reason how these two gaps should interact at the different stages and thus can better guide how the agentic system evolves.
To consider this trade-off, I developed a two-stage self-balancing guide approach. In the first stage when the agent is still collecting external information, it does a bit of generation gap optimization. Once it’s done collecting the external information, it moves onto the second stage of the final report generation, it does the full generation gap optimization.
In the first stage, by analyzing the information gap in the draft report and current findings, it either generates section-based queries or global context based queries. The information gap is defined by a set of rules such as comprehensiveness rules, and simplified insight rules. This set of rules govern how the draft report maintains its context. However, we also have other considerations such as token cost and latency, so in the first stage, I also consider the scaling rules and related latency rules. I find during the draft report refinement stage, it’s important not to consider Helpfulness rules. For example, the Helpfulness rules say it should always write in a paragraph form, not bullet points. Focusing on readability and complex insight rules tends to introduce unnecessary details, which wastes the precious context space. So instead, I let it keep in bullet points and in simple language. This helps the model focus on keeping track of a list of most critical details and insights in the information collection stage while doing a bit generation gap closing.
In the second stage, I include the Helpfulness Rules and full Insightfulness Rules (both rules are mentioned in Self-Balancing Agentic AI section) to make sure it fully utilize the collected information to generate the final report. The key here is to make sure the final report generation does not miss any important information when synthesizing the final report in a more human readability format. Helpfulness rules address this readability gap. I also find that it’s crucial to have a more complex Insightfulness Rules at the final report generation stage to ask it to think more deeply and analytically.
Self-Balancing Agentic AI and Context Engineering
One of the most critical challenges in building a context-aware agent is managing an ever-growing conversation history. In theory, models with large context windows can handle extensive transcripts; in practice, as the context grows, cost and latency increase. Additionally, models can suffer from “context rot,” a phenomenon where their ability to pay attention to critical information diminishes as context grows. Context Engineering directly addresses this by employing strategies to dynamically mutate the history to preserve vital information while managing the overall token count, ultimately leading to more robust AI experiences. [7]
Often with long horizon tasks, the agent system encounters the following issues:
Context Poisoning: When a hallucination makes it into the context
Context Distraction: When the context overwhelms the training
Context Confusion: When superfluous context influences the response
One way to address those issues is to make multiple sub-agents operate in parallel with their own context windows, exploring different aspects of the question simultaneously. This is commonly known as context isolation [8] [9]. Once enough information is collected by the sub-agents, the supervisor agent refines the draft report with those new information.
Our key innovation is that ThinkDepth.ai deep research uses the draft report as the additional context in a self-balancing manner. It saves the most critical information in that draft report by balancing among the different high-level rules. This approach is very similar to how humans develop things. We have an initial prototype and we gradually add features to it so that it satisfies all the constraints set by the high-level guiding rules [from customer’s or manager’s requirements]. Then, the draft report will guide the next round of external information collection.
The self-balancing rules however do not just govern the draft report refinement, it also govern overall context engineering. Context engineering does not just deal with the draft report, but all the other things that is outside of the model but needs to go into the model’s context window.
If the model is very capable of handling the task with its internal knowledge, it can skip all the structures and just launch one sub-agent to do one single external web search tool call and write the final report.
If the model’s internal knowledge is not enough to handle the task, it can follow the full Self-Balancing Test-Time Diffusion Deep Research algorithm and launch multiple sub-agents to do multiple web search tool calls to collect info and refine the draft report iteratively. It can also add additional steps such as writing code or doing calculation as long as they satisfy the constraints set by the self-balancing rules. And those additional steps are not specified by provided structures in the prompt or in the agentic system design.
The Self-Balancing Agentic AI thus enables the model to fully unleash its power if it’s capable for that task; if the model needs help, it can fall back to rely on the provided structures as the guide; most importantly, it can go beyond what the structures provide to create or remove things as long as they satisfy the constraints set by the self-balancing guiding rules.
Results
With those innovations, ThinkDepth.ai deep researcher is ranked #1 on the DeepResearch Bench [10]. ThinkDepth.ai deep research established a new state-of-art result on DeepResearch Bench on Oct 29th, 2025. It outperformed Google Gemini 2.5 pro deep research by 2.78%; outperformed OpenAI deep research by 6.04%; and outperformed Anthropic Claude deep research by 7.45%. See the overall_score chart.
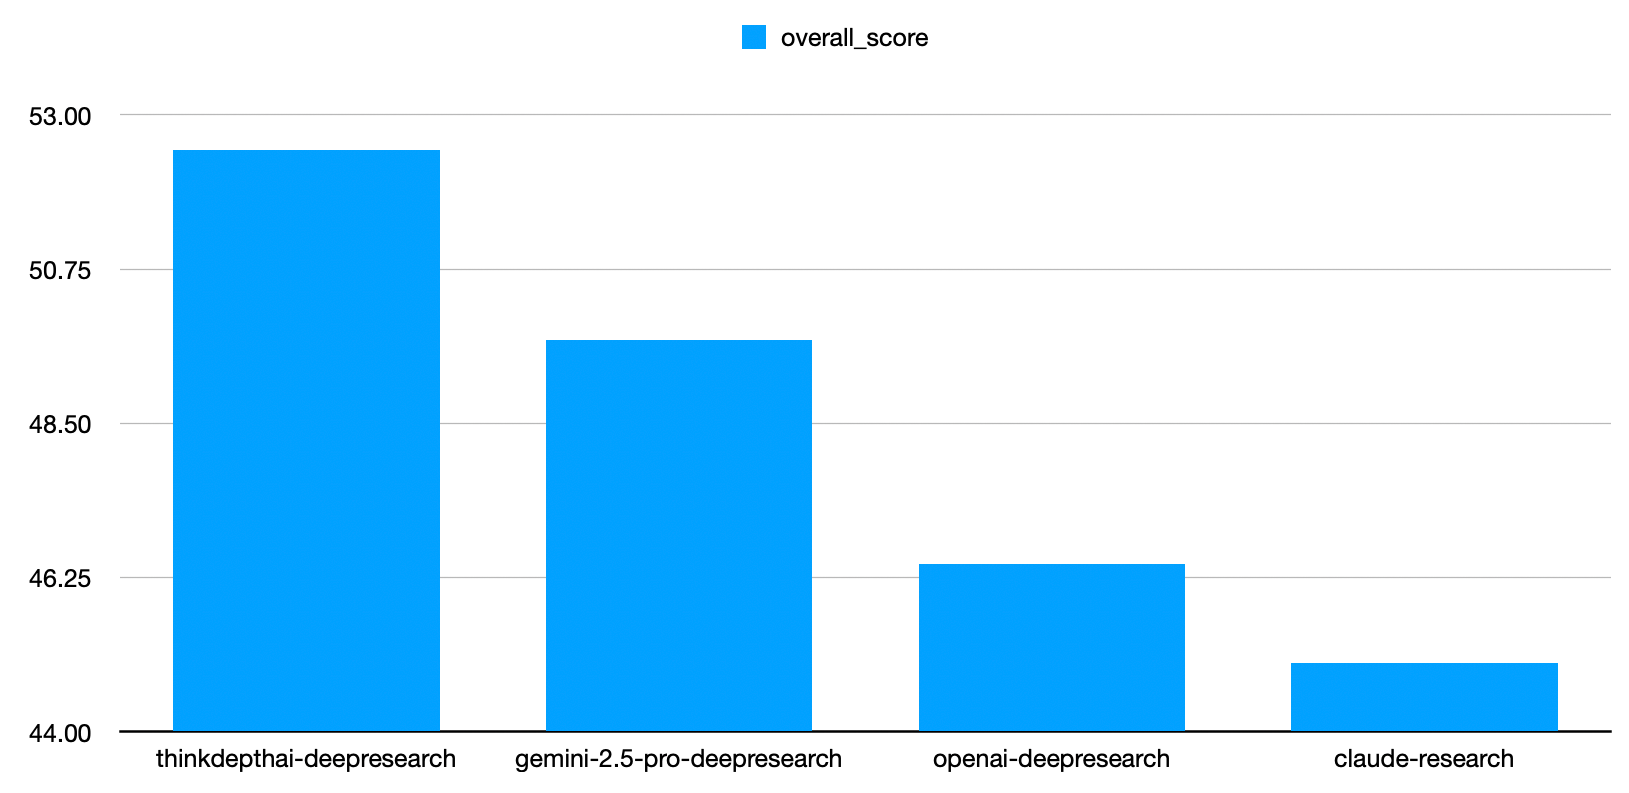
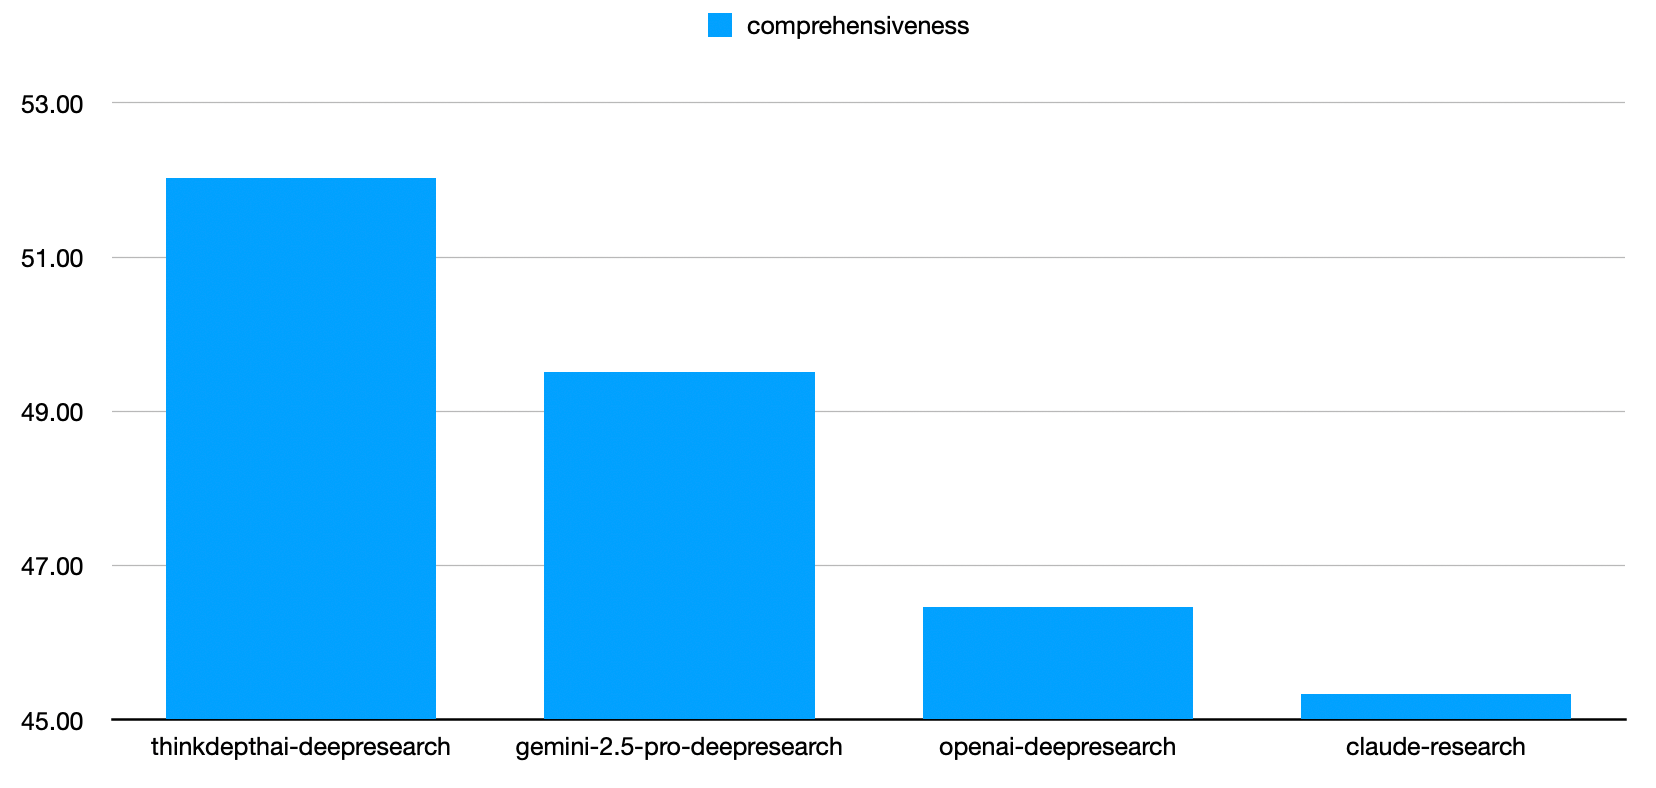
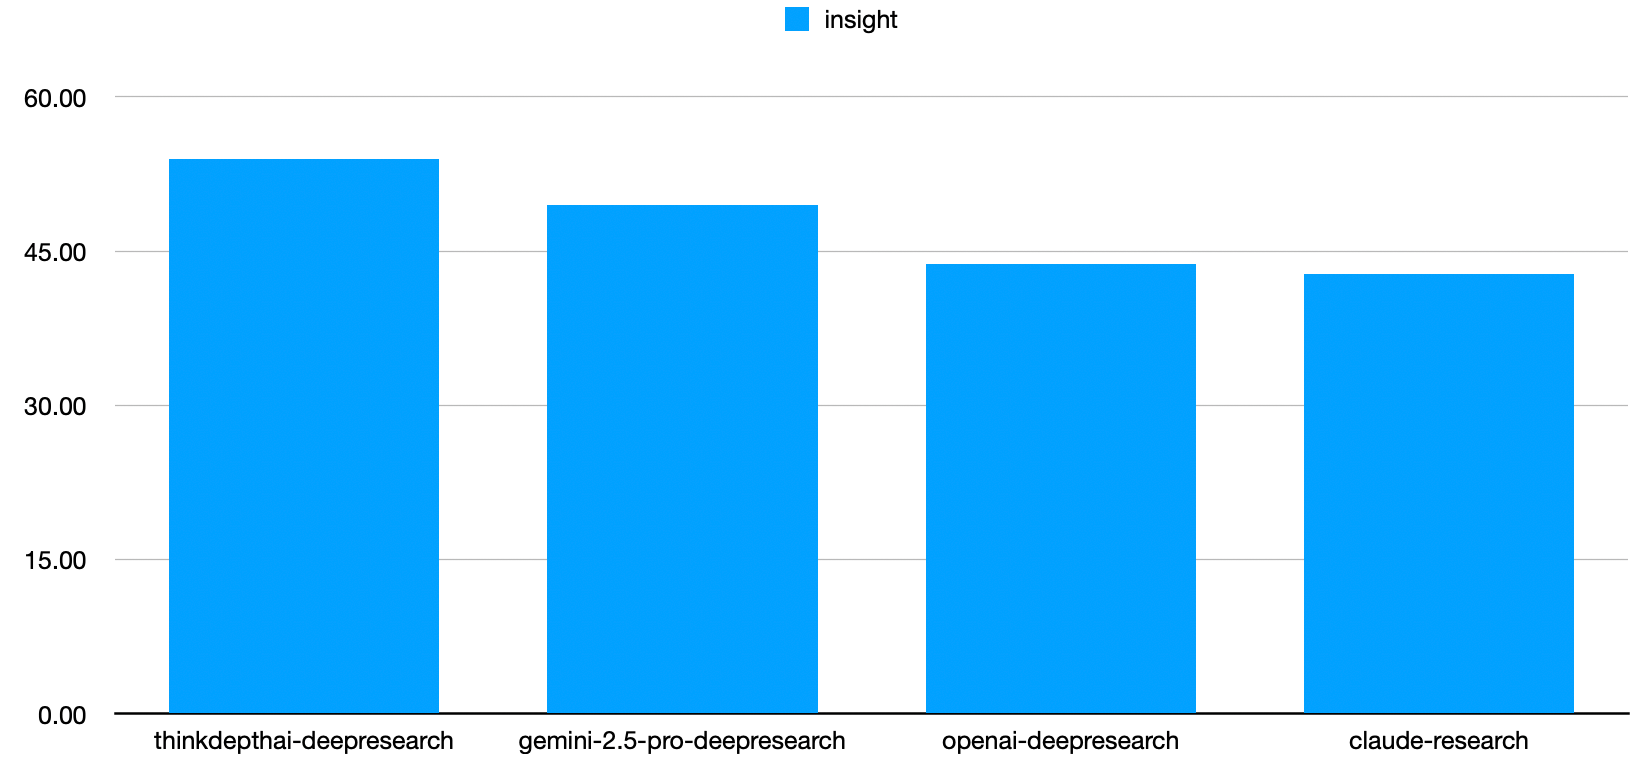
To demonstrate that ThinkDepth.ai deep research can close the information gap better, I include the Comprehensiveness score and Insight score results.
We see that ThinkDepth.ai deep research’s Comprehensiveness score is 52.03. It outperformed Google Gemini 2.5 pro deep research by 3.02%; outperformed OpenAI deep research by 5.57%; and outperformed Anthropic Claude deep research by 6.69%. See the comprehensiveness chart.
We see that ThinkDepth.ai deep research’s Insight score is 53.94. It outperformed Google Gemini 2.5 pro deep research by 4.49%; outperformed OpenAI deep research by 10.21%; and outperformed Anthropic Claude deep research by 11.15%. See the insight chart.
This shows ThinkDepth.ai deep research can close the information gap much better by getting more comprehensive coverage and depth of the information.
To demonstrate that ThinkDepth.ai deep research can close the generation gap better, I include the Instruction Following score and Readability score results.
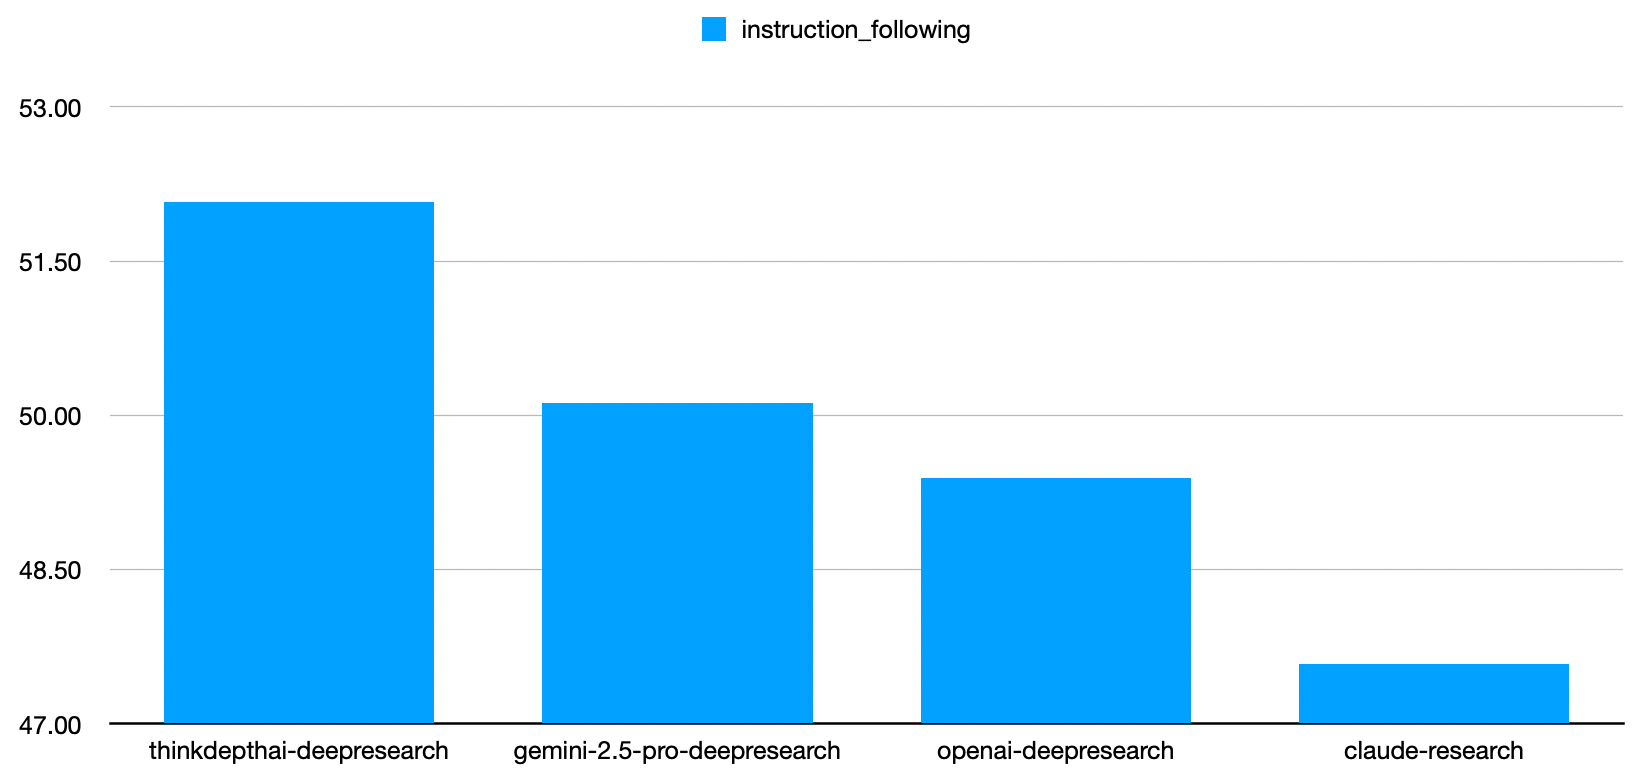
We see that ThinkDepth.ai deep research’s Instruction Following score is 52.07. It outperformed Google Gemini 2.5 pro deep research by 1.95%; outperformed OpenAI deep research by 2.68%; and outperformed Anthropic Claude deep research by 4.49%. See the instruction_following chart.
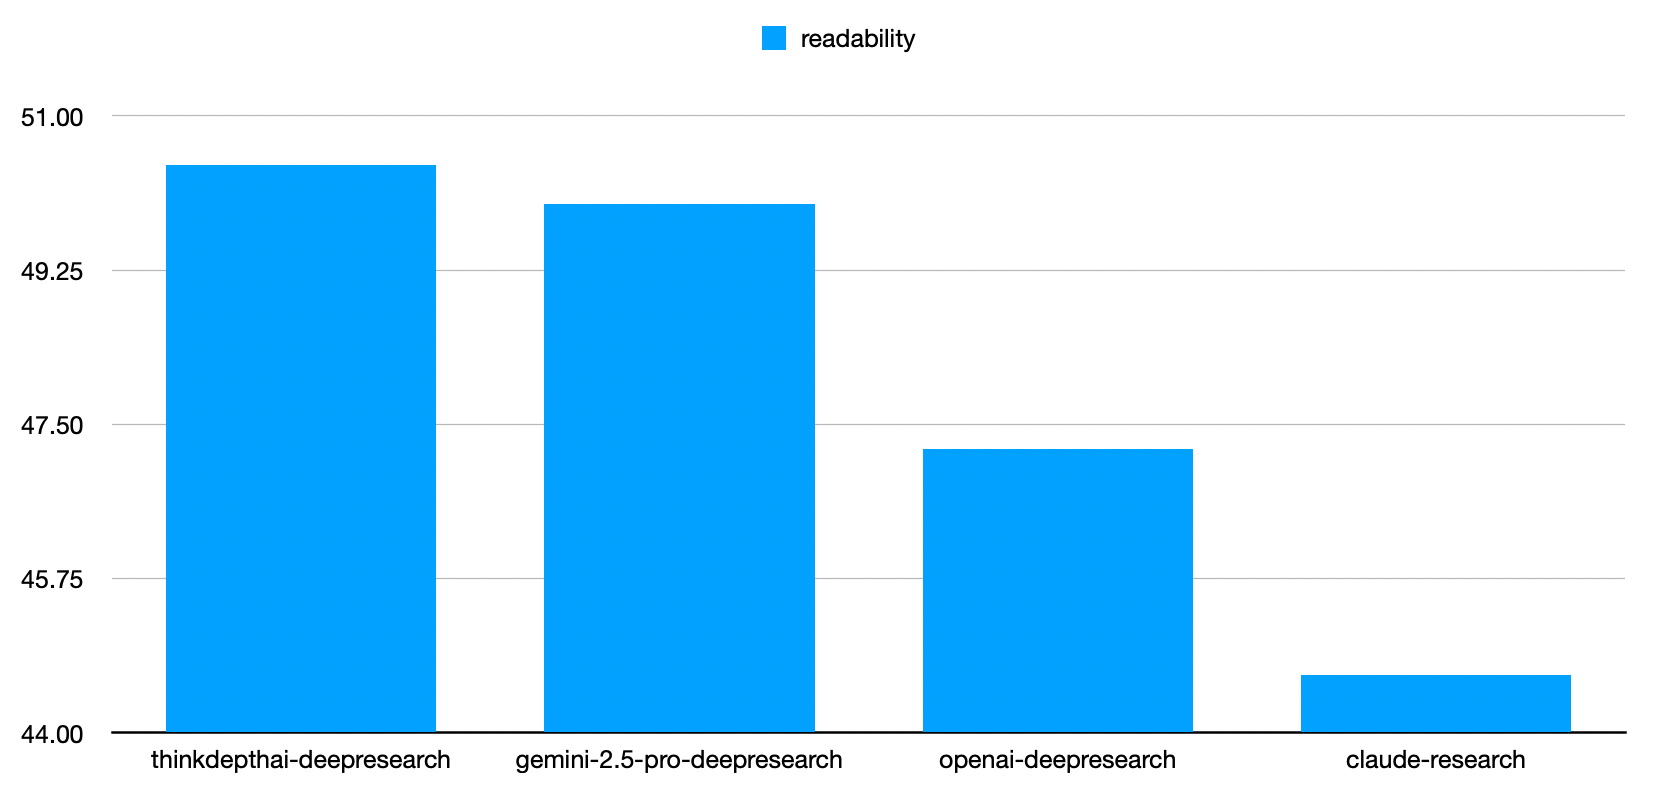
We see that ThinkDepth.ai deep research’s Readability score is 50.44. It outperformed Google Gemini 2.5 pro deep research by 0.44%; outperformed OpenAI deep research by 3.22%; and outperformed Anthropic Claude deep research by 5.78%. See the readability chart.
This shows ThinkDepth.ai deep research can close the generation gap much better by generating more helpful and readable information to the users.
Conclusion
Self-Balancing Agentic AI applied to deep research allows it to 1) address the issue of balancing multiple factors for long horizon and complex tasks and to 2) address the issue of balancing between model capability and structural flexibility.
It enables the Agentic AI developer to more explicitly reason about the self-balancing rules that guide the interaction of different requirements at different stages. For example, it allows ThinkDepth.ai deep research to explicitly guide the interaction between information gap closing and generation gap closing at different stages.
ThinkDepth.ai has fully open sourced its deep research system on GitHub [11].
References
[1] OpenAI Deep Research, OpenAI
[2] Deep Researcher with Test-Time Diffusion, Google
[3] Open Deep Research, LangChain
[4] The Bitter Lesson, Richard Sutton
[5] Shaping the Future of AI from the History of Transformer, Hyung Won Chung
[6] Why language models hallucinate, OpenAI
[7] Context Engineering: Sessions, Memory, Google
[8] Context Engineering for Agents, Lance Martin
[9] How we built our multi-agent research system, Anthropic
[10] DeepResearch Bench: A Comprehensive Benchmark for Deep Research Agents, Mingxuan Du, Benfeng Xu, Chiwei Zhu, Xiaorui Wang, Zhendong Mao